Anatomy of a 5-minute AI narrative: "Your Life as One Coffee Bean"
A full teardown of the reference render - 8,420 characters of V3 script, 40 Nano Banana images, three music stems, a 3-pass ffmpeg render. With receipts.
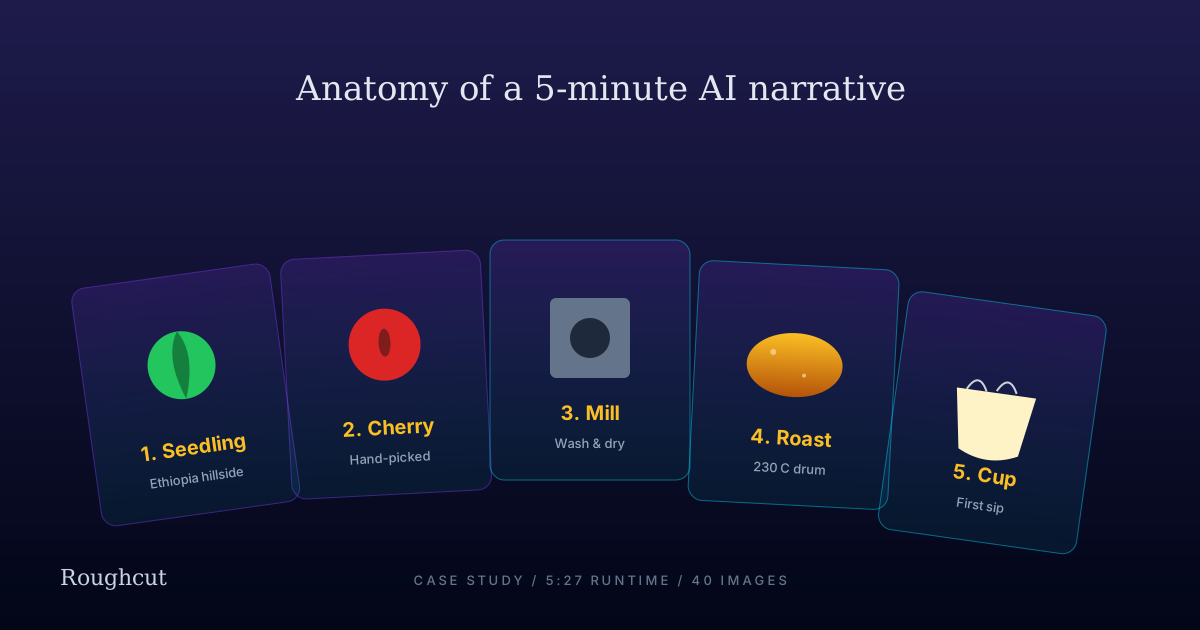
The "Your Life as One Coffee Bean" video is a five-minute, twenty-seven second POV narrative that ships as the reference render with every VideoCue install. It exists for one reason: it is the most honest answer to "what does a finished video out of this thing look like?"
Here is the teardown, end to end, with the actual numbers.
The five-act structure
The whole piece is organised around the path of a single bean. We picked the structure first, then wrote toward it.
- Seedling (0:00 – 0:58) - A coffee cherry ripening on a tree in Yirgacheffe. POV of the bean inside the fruit, sensing morning, weight, the hand that picks.
- Cherry (0:58 – 2:04) - Sorted, fermented, washed. Texture and water. The smell of wet pulp.
- Mill (2:04 – 2:58) - Dried on raised beds, hulled, graded. The sound changes from wet to dry, soft to hard.
- Roast (2:58 – 4:12) - A small-batch roaster in a back-street workshop in Brooklyn. Heat, oil, the first and second crack.
- Cup (4:12 – 5:27) - Ground, dosed, pulled. A barista's hand on the lever. A commuter's first sip.
Each act has a different sensory register. The script keeps tagging that register so the voice and images don't drift.
The script
The full V3-marked script is 8,420 characters across 64 lines, broken into 8 generation chunks of roughly 1,050 characters each (V3's effective sweet spot is 1,000–1,500 chars per generation; quality drops past about 4,000).
A representative chunk from Act 3 - Mill:
[contemplative] You are no longer inside the cherry.

[pause] The fruit is gone. Pulled away. Washed down a long channel of cold water and into a pile of skin and seed.

What is left of you is a green bean. [exhales] Small. Hard. Quiet.

The sun finds you on a raised bed. [pause] You dry, slowly, for twelve days.

You can hear the bed. You can hear the wind. You can hear, somewhere far below, a child laughing.
The tags are doing real work. [contemplative] lowers the baseline pitch and slows attack. [pause] inserts about 600ms of dead air without dropping the voice's tonal continuity. [exhales] adds a breath without breaking the line. We use [long pause] only twice in the whole script, at act breaks.
Voice generation - numbers
- Voice: Bradford on ElevenLabs V3
- Stability: Natural (a touch of warmth tolerance)
- Style: 0 (no exaggeration - we want him to sound like a person, not a Voice Actor)
- Speaker boost: on
- Chunks: 8 at 700–1,200 characters each
- Total VO duration: 5:11
- Generation wall time: 2 minutes 14 seconds for all eight chunks
- Pass rate: 6 of 8 first time; one chunk re-rolled for a swallowed consonant, one for a pacing dip
- Provider cost: $1.35 at current V3 character pricing
The Bradford voice was chosen during the pre-build phase by listening to 30 second samples of 14 candidate voices reading the Seedling block. Bradford was the only one that did not "perform" - he just narrated. The whole video pivots on that decision.
Image generation
40 hero frames at 1920×1080, generated via Gemini 2.5 Flash Image (Nano Banana). The protocol:
- We picked a single anchor frame - a macro of a wet coffee cherry held in a calloused hand, golden hour, warm earth-tone grade.
- We extracted a style suffix from that frame:
"warm earth tones, 35mm film grain, golden hour light, shallow depth of field, slightly desaturated highlights, cinematic". - Every subsequent prompt carries that suffix verbatim.
- The first ten frames also reference the anchor as an image input (Gemini's reference-image mode). After ten frames, the palette has stabilised and we drop the reference, which saves cost on the remaining thirty.
Sample prompt (Roast, frame 28):
A small commercial drum roaster in a brick-walled Brooklyn workshop,
beans cascading mid-roast in the drum, single bulb above casting warm amber light,
soft haze of bean dust in the air, hand of an out-of-frame roaster holding a sampling trier,
shallow depth of field, focus on the falling beans,
warm earth tones, 35mm film grain, golden hour light, shallow depth of field,
slightly desaturated highlights, cinematic.
Total cost across 40 images: $0.40. Time: 6 minutes (with three rerolls).
We post about how this anchoring works in detail here.
Music
Three stems, chosen by the editor in about 90 seconds:
- A slow piano cue under Seedling and Cherry (Acts 1 and 2)
- A low-string pad with sparse percussion under Mill and Roast (Acts 3 and 4)
- A solo cello line that resolves to a single sustained note under Cup (Act 5)
The pipeline's automatic side-chain ducking pulls the stems down 6–8 dB whenever the voice is active. We did one manual tweak - the cello swell at 5:08 was lifted 2 dB during a silent VO beat so it could breathe.
Cost: $0.30 across the three royalty-cleared cues.
Render - the three passes
The visible work happens in three ffmpeg passes:
- Pass 1 - image-to-clip. Each of the 40 hero frames becomes a Ken-Burns motion clip at the duration the cue boundary requires. 56 total fragments (some images get split across multiple cues). Wall time: 3 minutes 4 seconds.
- Pass 2 - concat with transitions. All 56 fragments stitched into a single video stream with crossfades at every act boundary and one harder cut on the first-sip moment at 4:18. Wall time: 5 minutes 12 seconds.
- Pass 3 - overlay + audio + watermark. Lower-third title at 0:00, end card at 5:18, audio stems mixed under the VO with side-chain. Output: 1080p H.264, 8 Mbps. Wall time: 3 minutes 1 second.
Total render wall time: 11 minutes 17 seconds, on a single mid-tier render worker (4 vCPU, 8GB RAM).
What the final file looks like
- Duration: 5:27
- Container: mp4
- Video: 1920×1080, 24 fps, H.264, ~8 Mbps
- Audio: 48 kHz stereo AAC, –16 LUFS integrated
- File size: 312 MB
- Provider pass-through cost end-to-end: $2.10
What we would change
Three notes from the editorial post-mortem:
- The Cherry act is half a minute too long. Sensory writing earns its runtime, but the fermentation beat at 1:34 lingers without paying off. We'd trim 22 seconds.
- Frame 19 (the wet pulp pile) is a dud. Composition is fine but the color saturation drifted. Worth a re-roll.
- The end card is too quiet. The barista's hand pulling the lever at 5:14 wants 4 dB more music, not less. Subjective; we left it.
The reference video is intentionally not "perfect" - we want it to look like a real piece of work, with the same kinds of choices a creator would make.
What to read next
- Writing for V3: ElevenLabs voice markup we actually use - the markup conventions in this script, explained.
- Style anchoring: how to keep 40 AI images consistent - the protocol that produced the 40 frames above.
- The 3-pass ffmpeg pipeline behind every VideoCue render - what's happening inside the render container.
Want to try the template that produced this video? POV Narrative is on every plan, including Free.